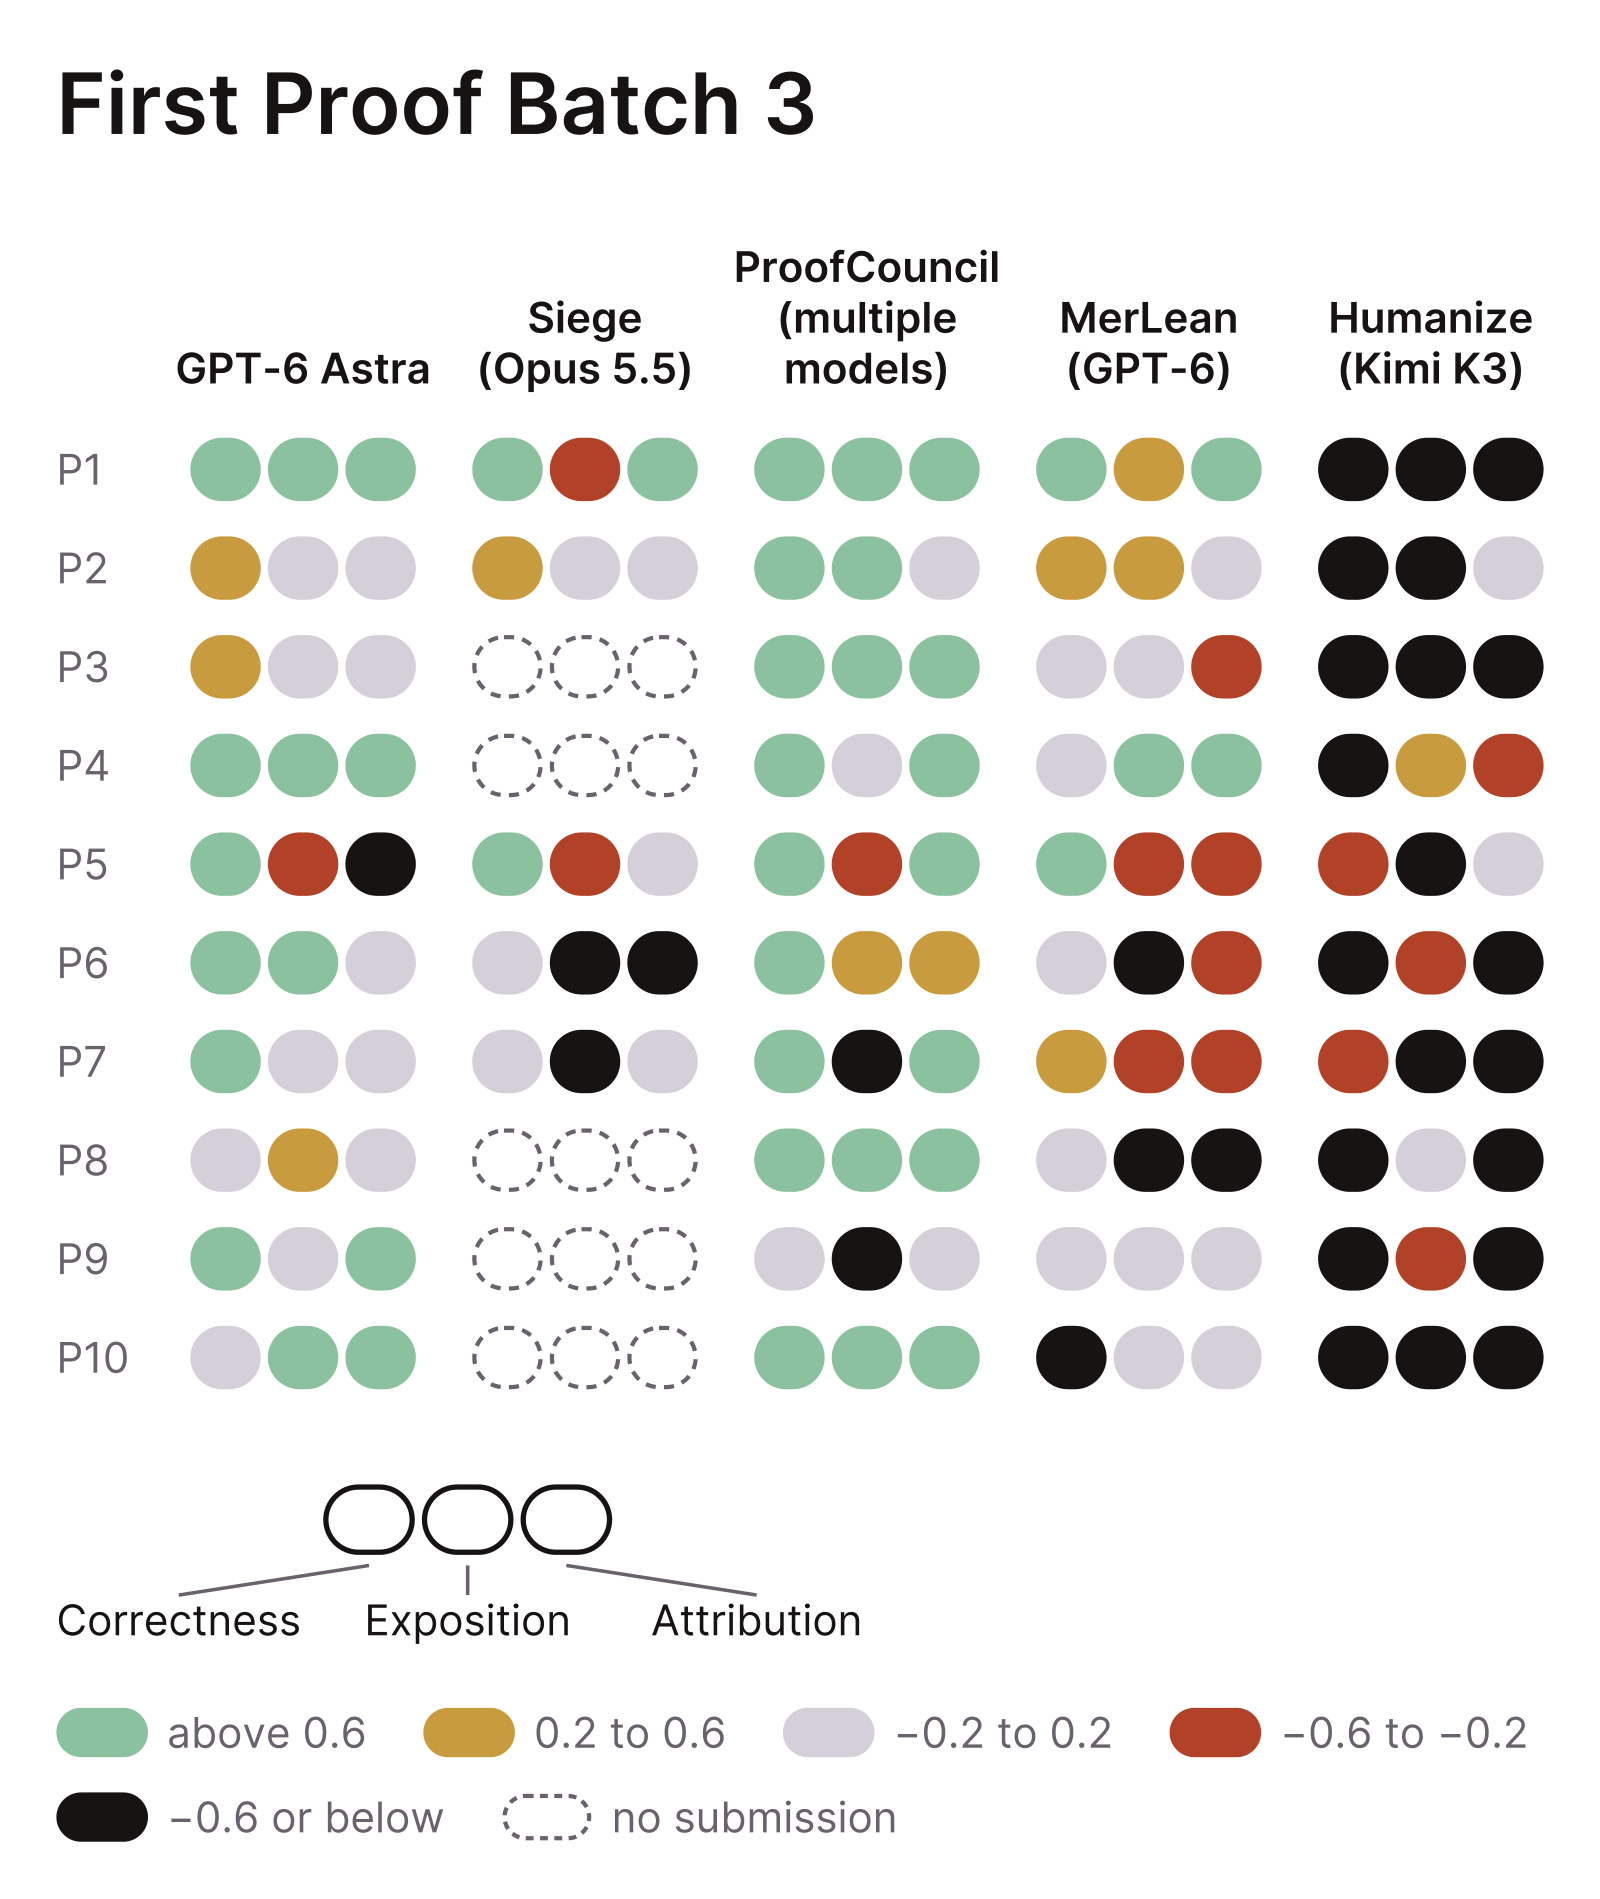
Third Batch Benchmark
The Third Batch Benchmark will test AI systems on ten naturally occurring research math problems which have been solved by human mathematicians but whose solutions have not been made public.
Timeline
Problem selection
Mathematicians across fields submit unpublished problems with proofs of at most 12 pages. All submissions undergo a first round of refereeing, and 10 problems are selected for the benchmark.
Benchmark testing
The editorial board tests AI systems via API. Each system is an open source harness which calls publicly available models, and gets one shot per question with no additional interaction.
Benchmark grading
Roughly 30 expert referees review the AI solutions double blind, scoring correctness, exposition, and attribution separately. Results — including the problems, human solutions, referee reports, and editorial board scores — will be published on October 14, 2026.